Qwen 3.5 9B Local Apple
Qwen 3.5 9B Local Apple is a local AI stack for Local AI on Apple Silicon with a compact high-quality model. Run Qwen 3.5 9B locally on Apple Silicon for private chat and assistant use. It combines 4 components, is rated intermediate, and takes about 20 minutes to set up. Expect about $529 for the cheapest listed device that fits (Apple Mac Mini M4) and $0/month versus cloud.
- Cost
- $529
- Apple Mac Mini M4 · $0/mo vs cloud
- Difficulty
- intermediate
- Setup time
- ~20 min
- Use case
- Local AI on Apple Silicon with a compact high-quality model
What's in this stack
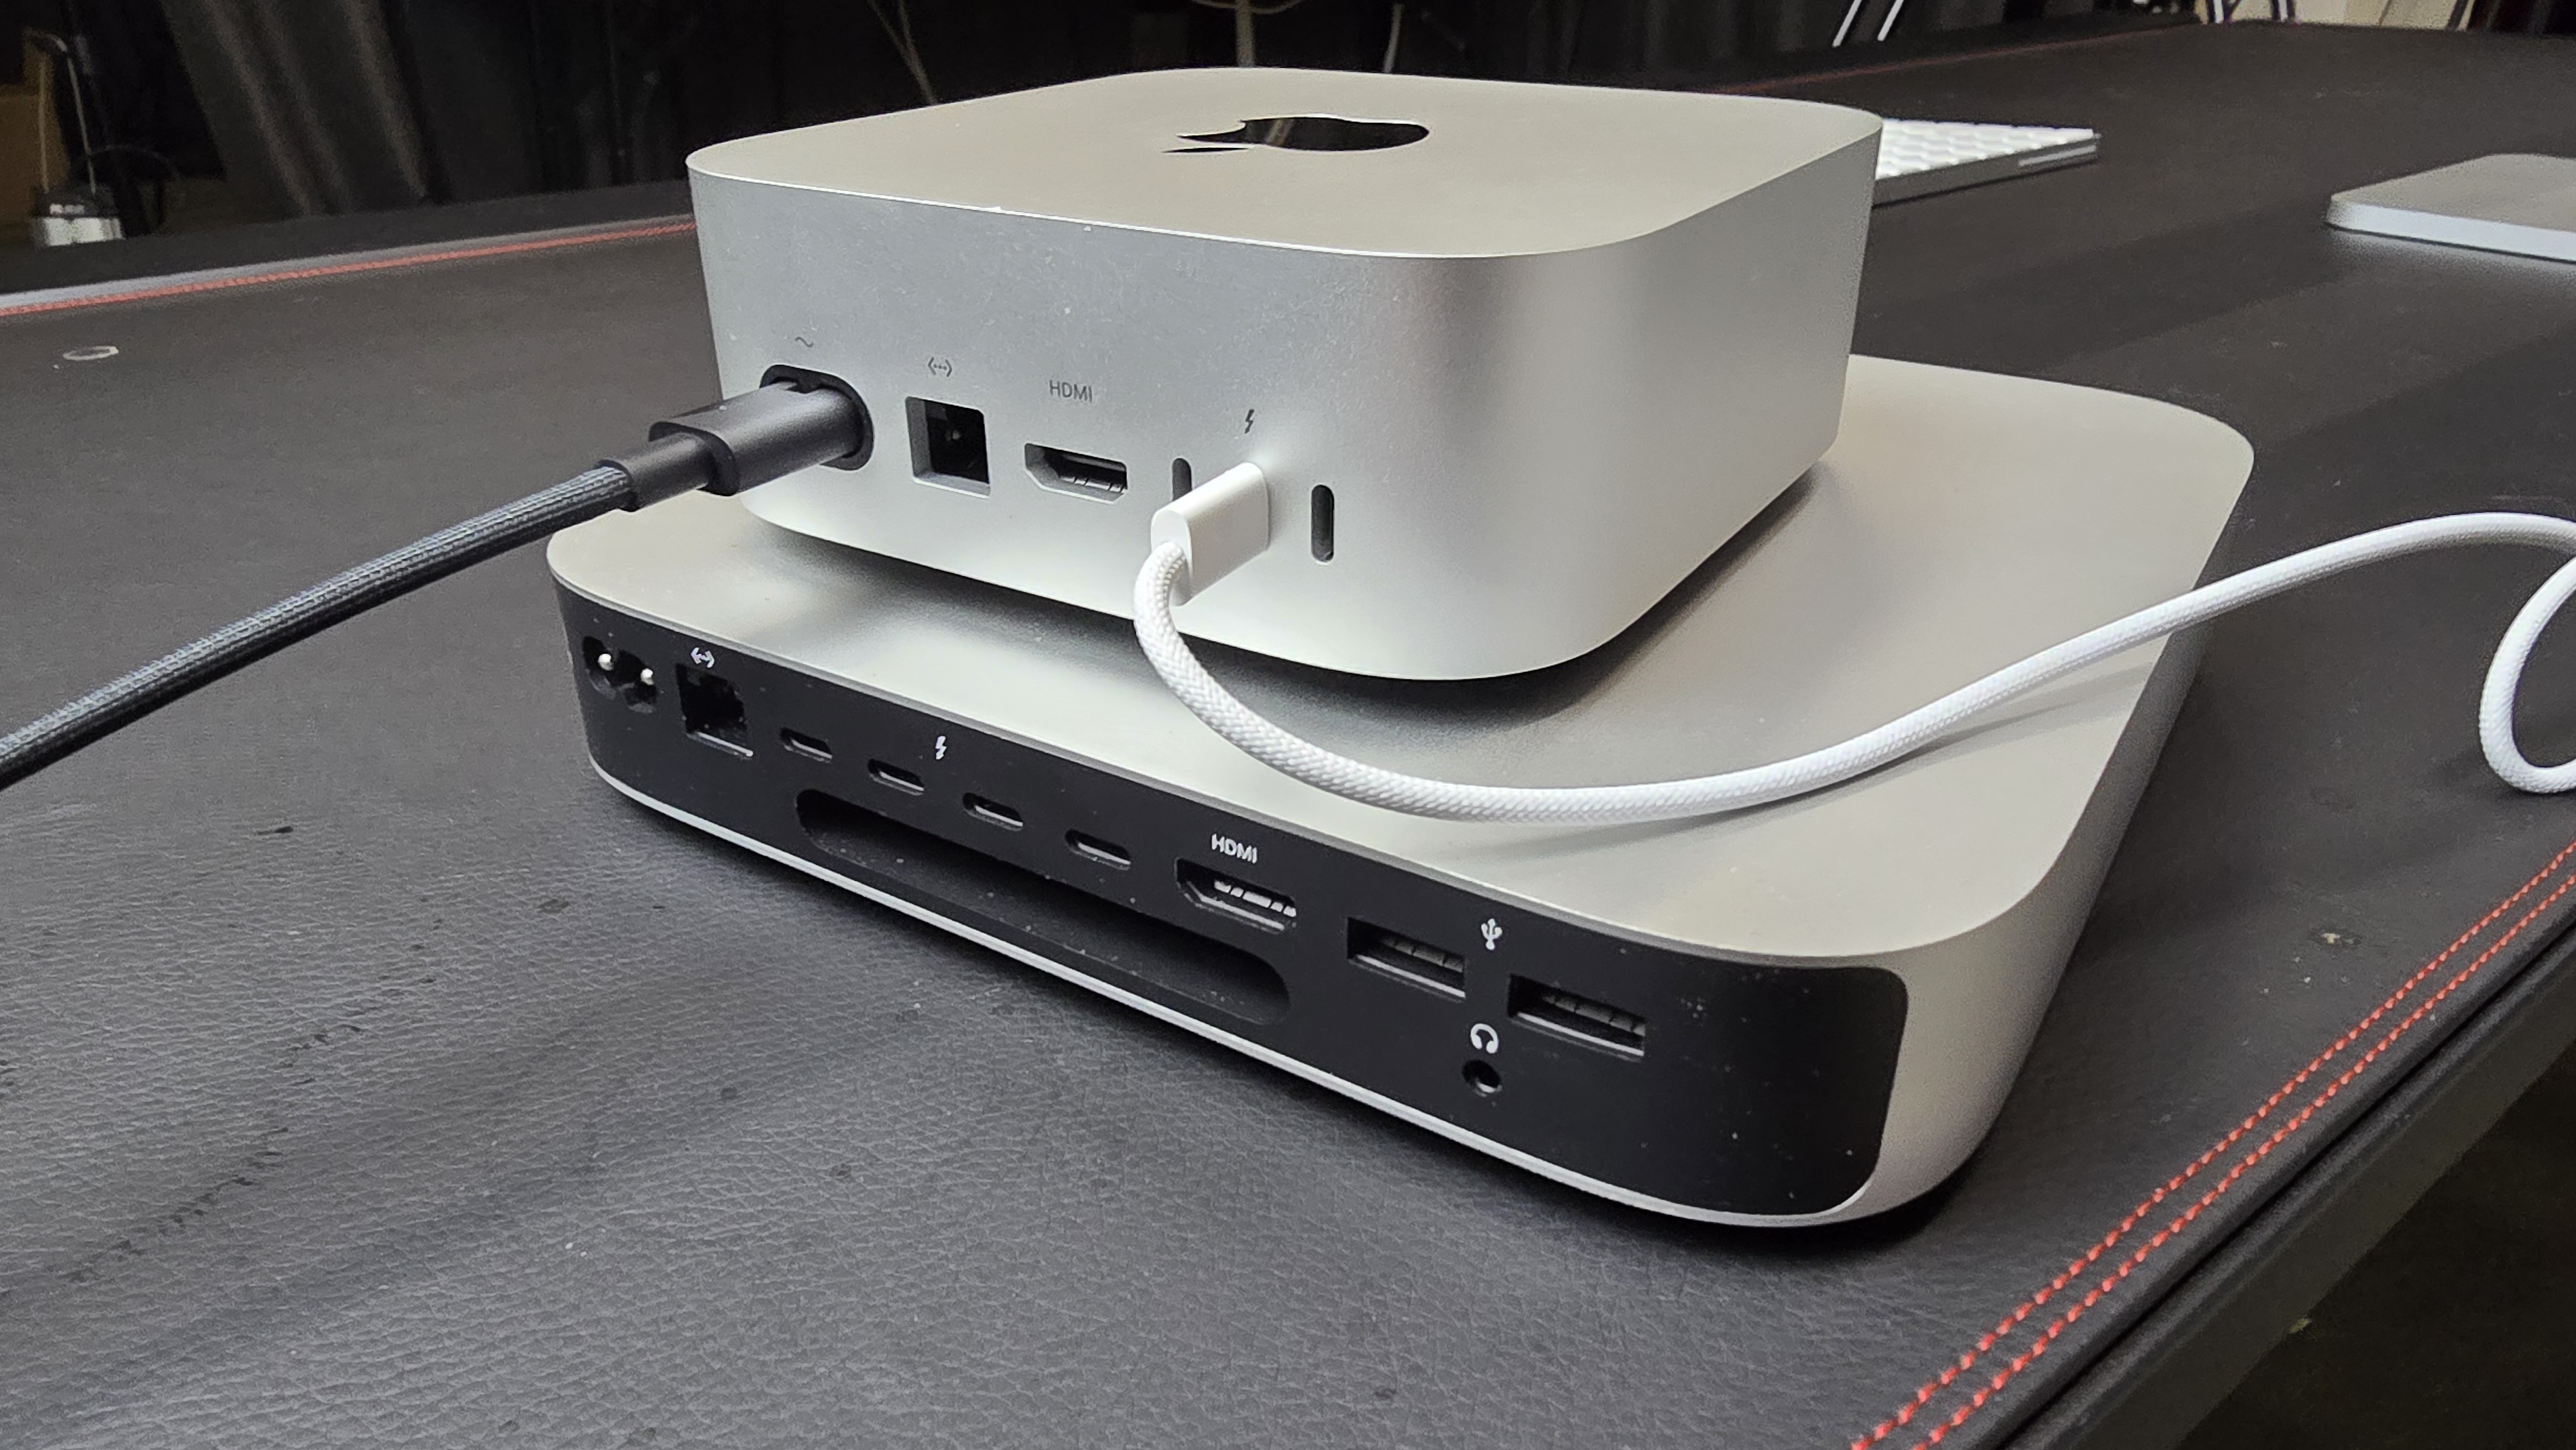 Apple Mac Mini M4
 Ollama
 omlx
Models are alternatives; fit is judged on the smallest (Q4_K_M weights + ~1.8 GB runtime overhead vs device memory). Speeds are for Llama 3 8B; "est." values are estimated from memory bandwidth.
Qwen 3.5 9B Local Apple
This stack runs Qwen 3.5 9B locally on Apple Silicon with Ollama and oMLX. It is a compact, responsive local model for privacy-first chat and assistant workflows.
What you get
- Fast local Qwen 3.5 inference on Mac hardware
- Private chat without cloud APIs
- A small enough model for Apple Silicon memory budgets
Architecture
| Component | Role |
|---|---|
| Ollama | Local model server |
| oMLX | Apple Silicon GPU optimization |
| Qwen 3.5 9B | Compact local model |
Prerequisites
- apple-mac-mini-m4 or similar Apple Silicon Mac
- 12+ GB free RAM for the model and system
- Ollama installed locally
Setup
brew install ollama
brew install omlx
ollama pull qwen3.5:9b
ollama serve --mlx
Open the local UI or use the API at http://localhost:11434.
Use it
- Daily local assistant for writing, planning, and code help.
- Private chat for sensitive work.
- Local agent launcher for small AI workflows.
Cost vs cloud
| Local | Cloud | |
|---|---|---|
| Monthly | $0 | $20+ |
| Hardware | $900 once | $0 |
| Privacy | High | Low |
Troubleshooting
- Model not loading → verify
ollama psand available Apple Silicon memory. - Slow inference → use
--mlxand confirm the model is running on the GPU. - Port block → make sure local port 11434 is open.
Swap components
- Use Open WebUI for a browser chat interface.
- For a larger local model, use Qwen 3.6 27B.
Frequently asked
What is the Qwen 3.5 9B Local Apple stack for?
Run Qwen 3.5 9B locally on Apple Silicon for private chat and assistant use. It is purpose-built for Local AI on Apple Silicon with a compact high-quality model and runs entirely on your own hardware.
How much does the Qwen 3.5 9B Local Apple stack cost?
Qwen 3.5 9B Local Apple costs about $529 for the cheapest listed device that fits (Apple Mac Mini M4) up front and $0/month to run, since everything is self-hosted — no per-token or subscription fees versus a cloud equivalent.
How long does it take to set up Qwen 3.5 9B Local Apple?
Plan for roughly 20 minutes. The stack is rated intermediate.
What do I need to run Qwen 3.5 9B Local Apple?
Qwen 3.5 9B Local Apple is built from 2 tool(s), 1 model(s), 1 hardware item(s). Each is listed below with a link.