Local Voice Assistant (Whisper + Ollama + Kokoro TTS)
Local Voice Assistant (Whisper + Ollama + Kokoro TTS) is a local AI stack for Build a private, always-on voice assistant that runs entirely on your hardware. Whisper.cpp + Ollama + Kokoro TTS = a fully local voice assistant. Speak, get AI answers spoken back. No cloud, no wake-word fees, runs on CPU. $0/mo. It combines 7 components, is rated advanced, and takes about 30 minutes to set up. Expect about $199 for the cheapest listed device that fits (NVIDIA RTX 3060 12GB) and $0/month versus cloud.
- Cost
- $199
- NVIDIA RTX 3060 12GB · $0/mo vs cloud
- Difficulty
- advanced
- Setup time
- ~30 min
- Use case
- Build a private, always-on voice assistant that runs entirely on your hardware
What's in this stack
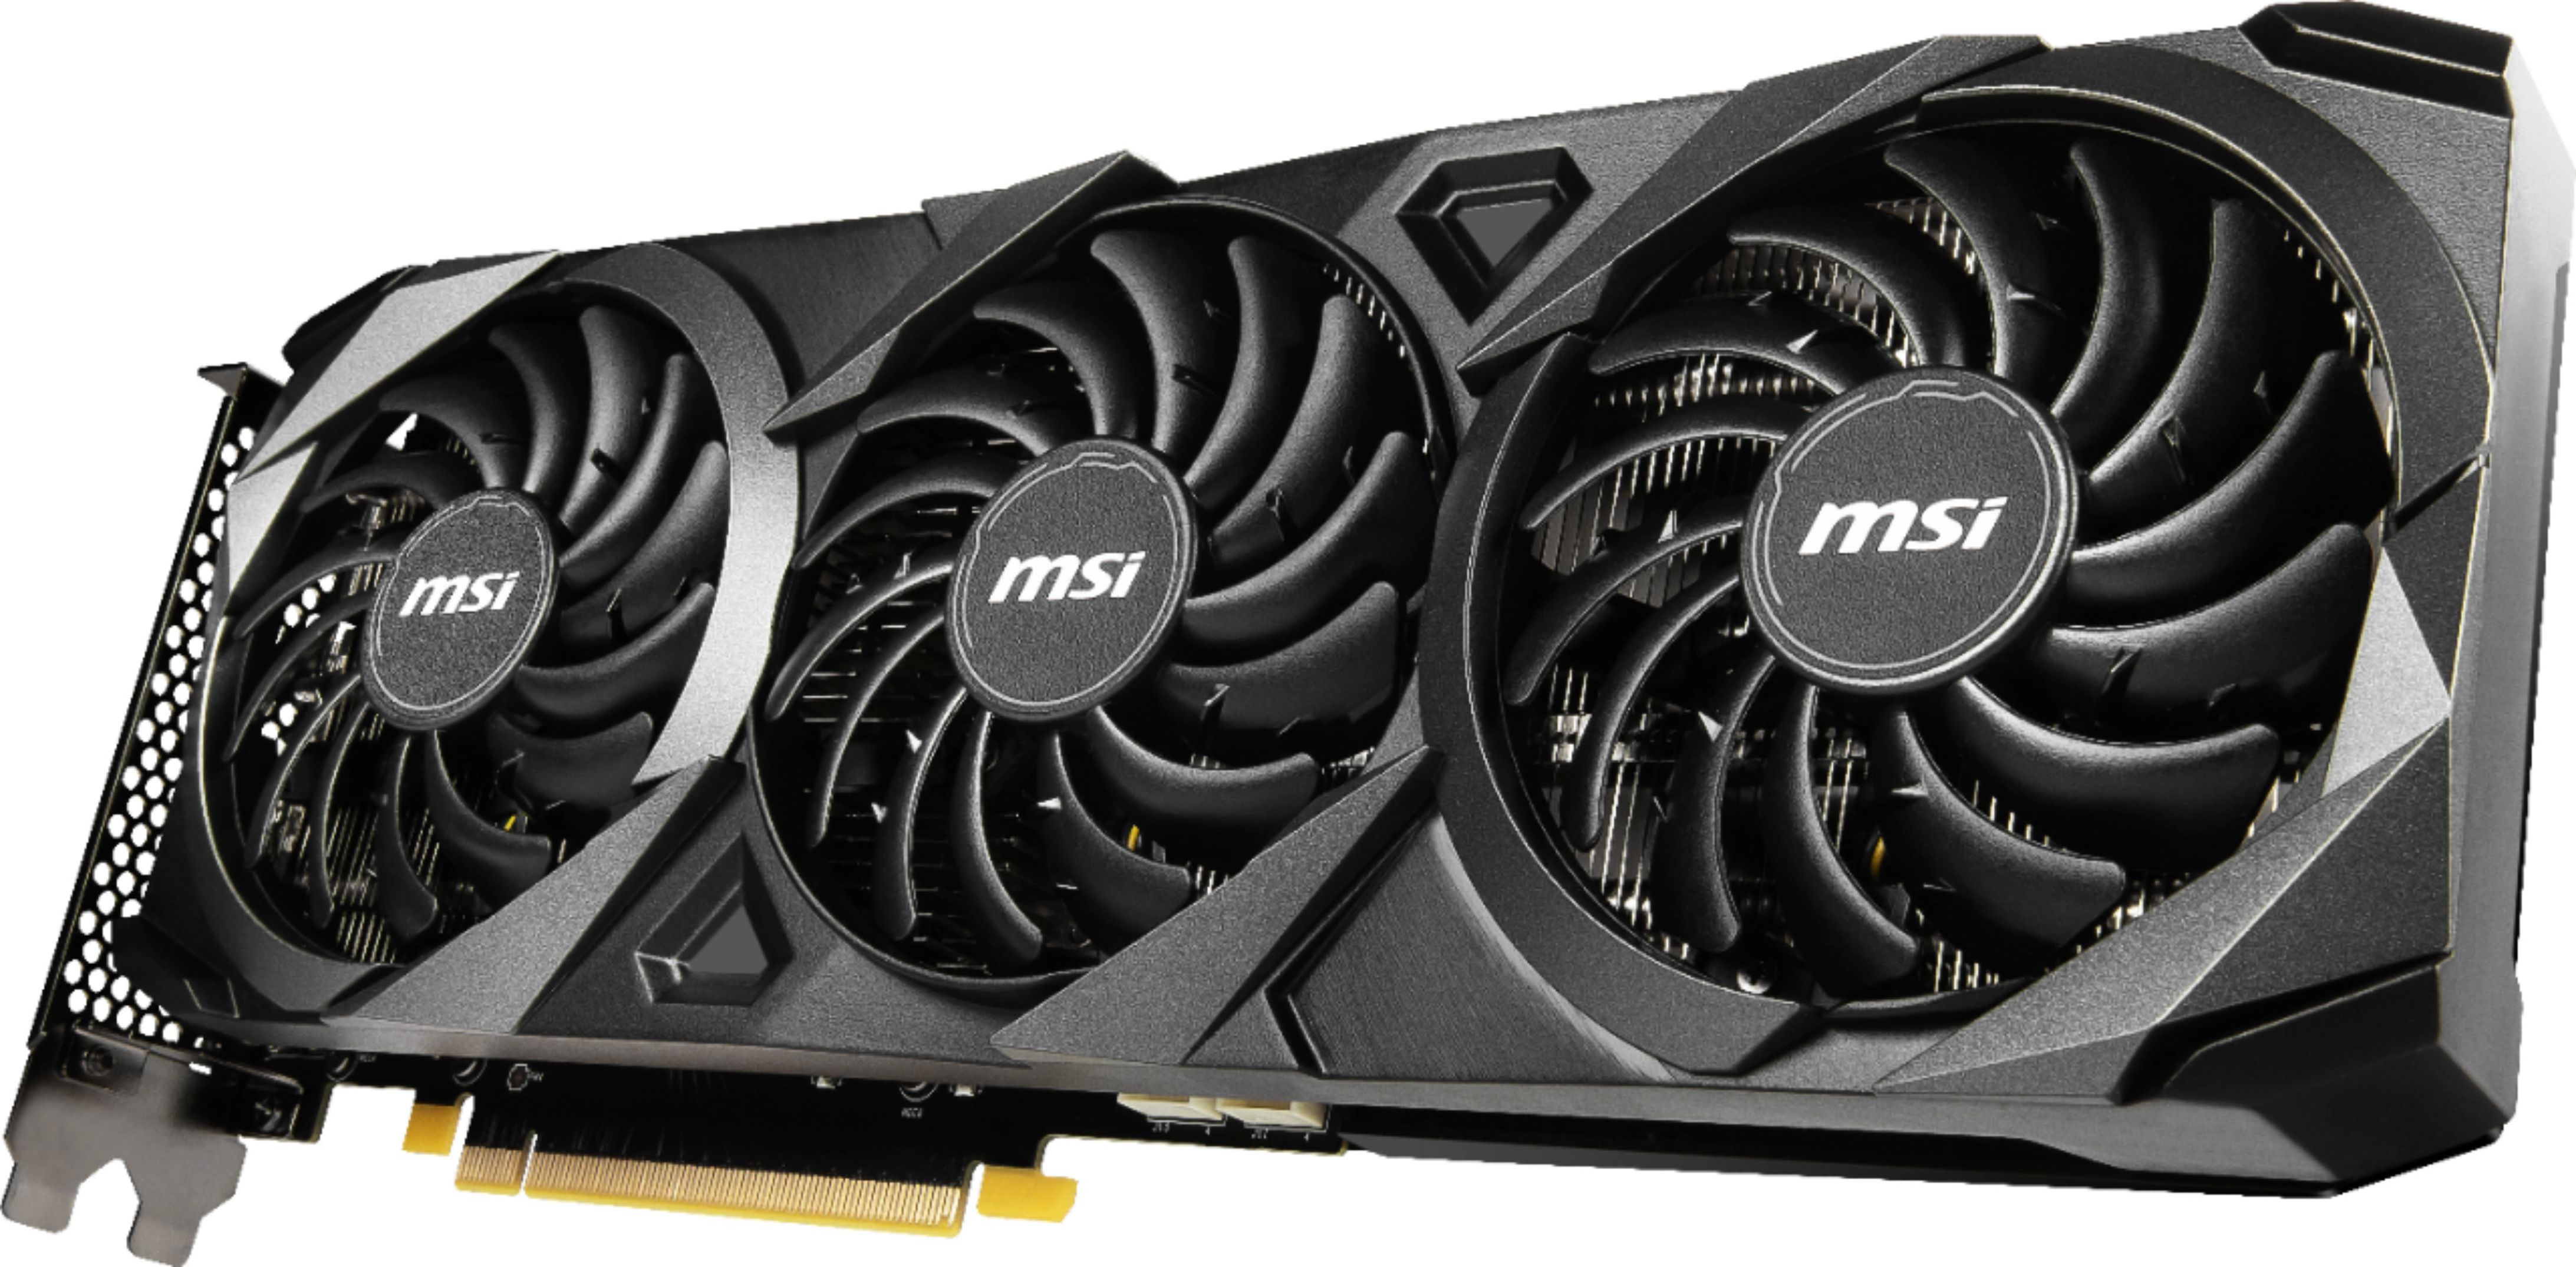 NVIDIA RTX 3060 12GB
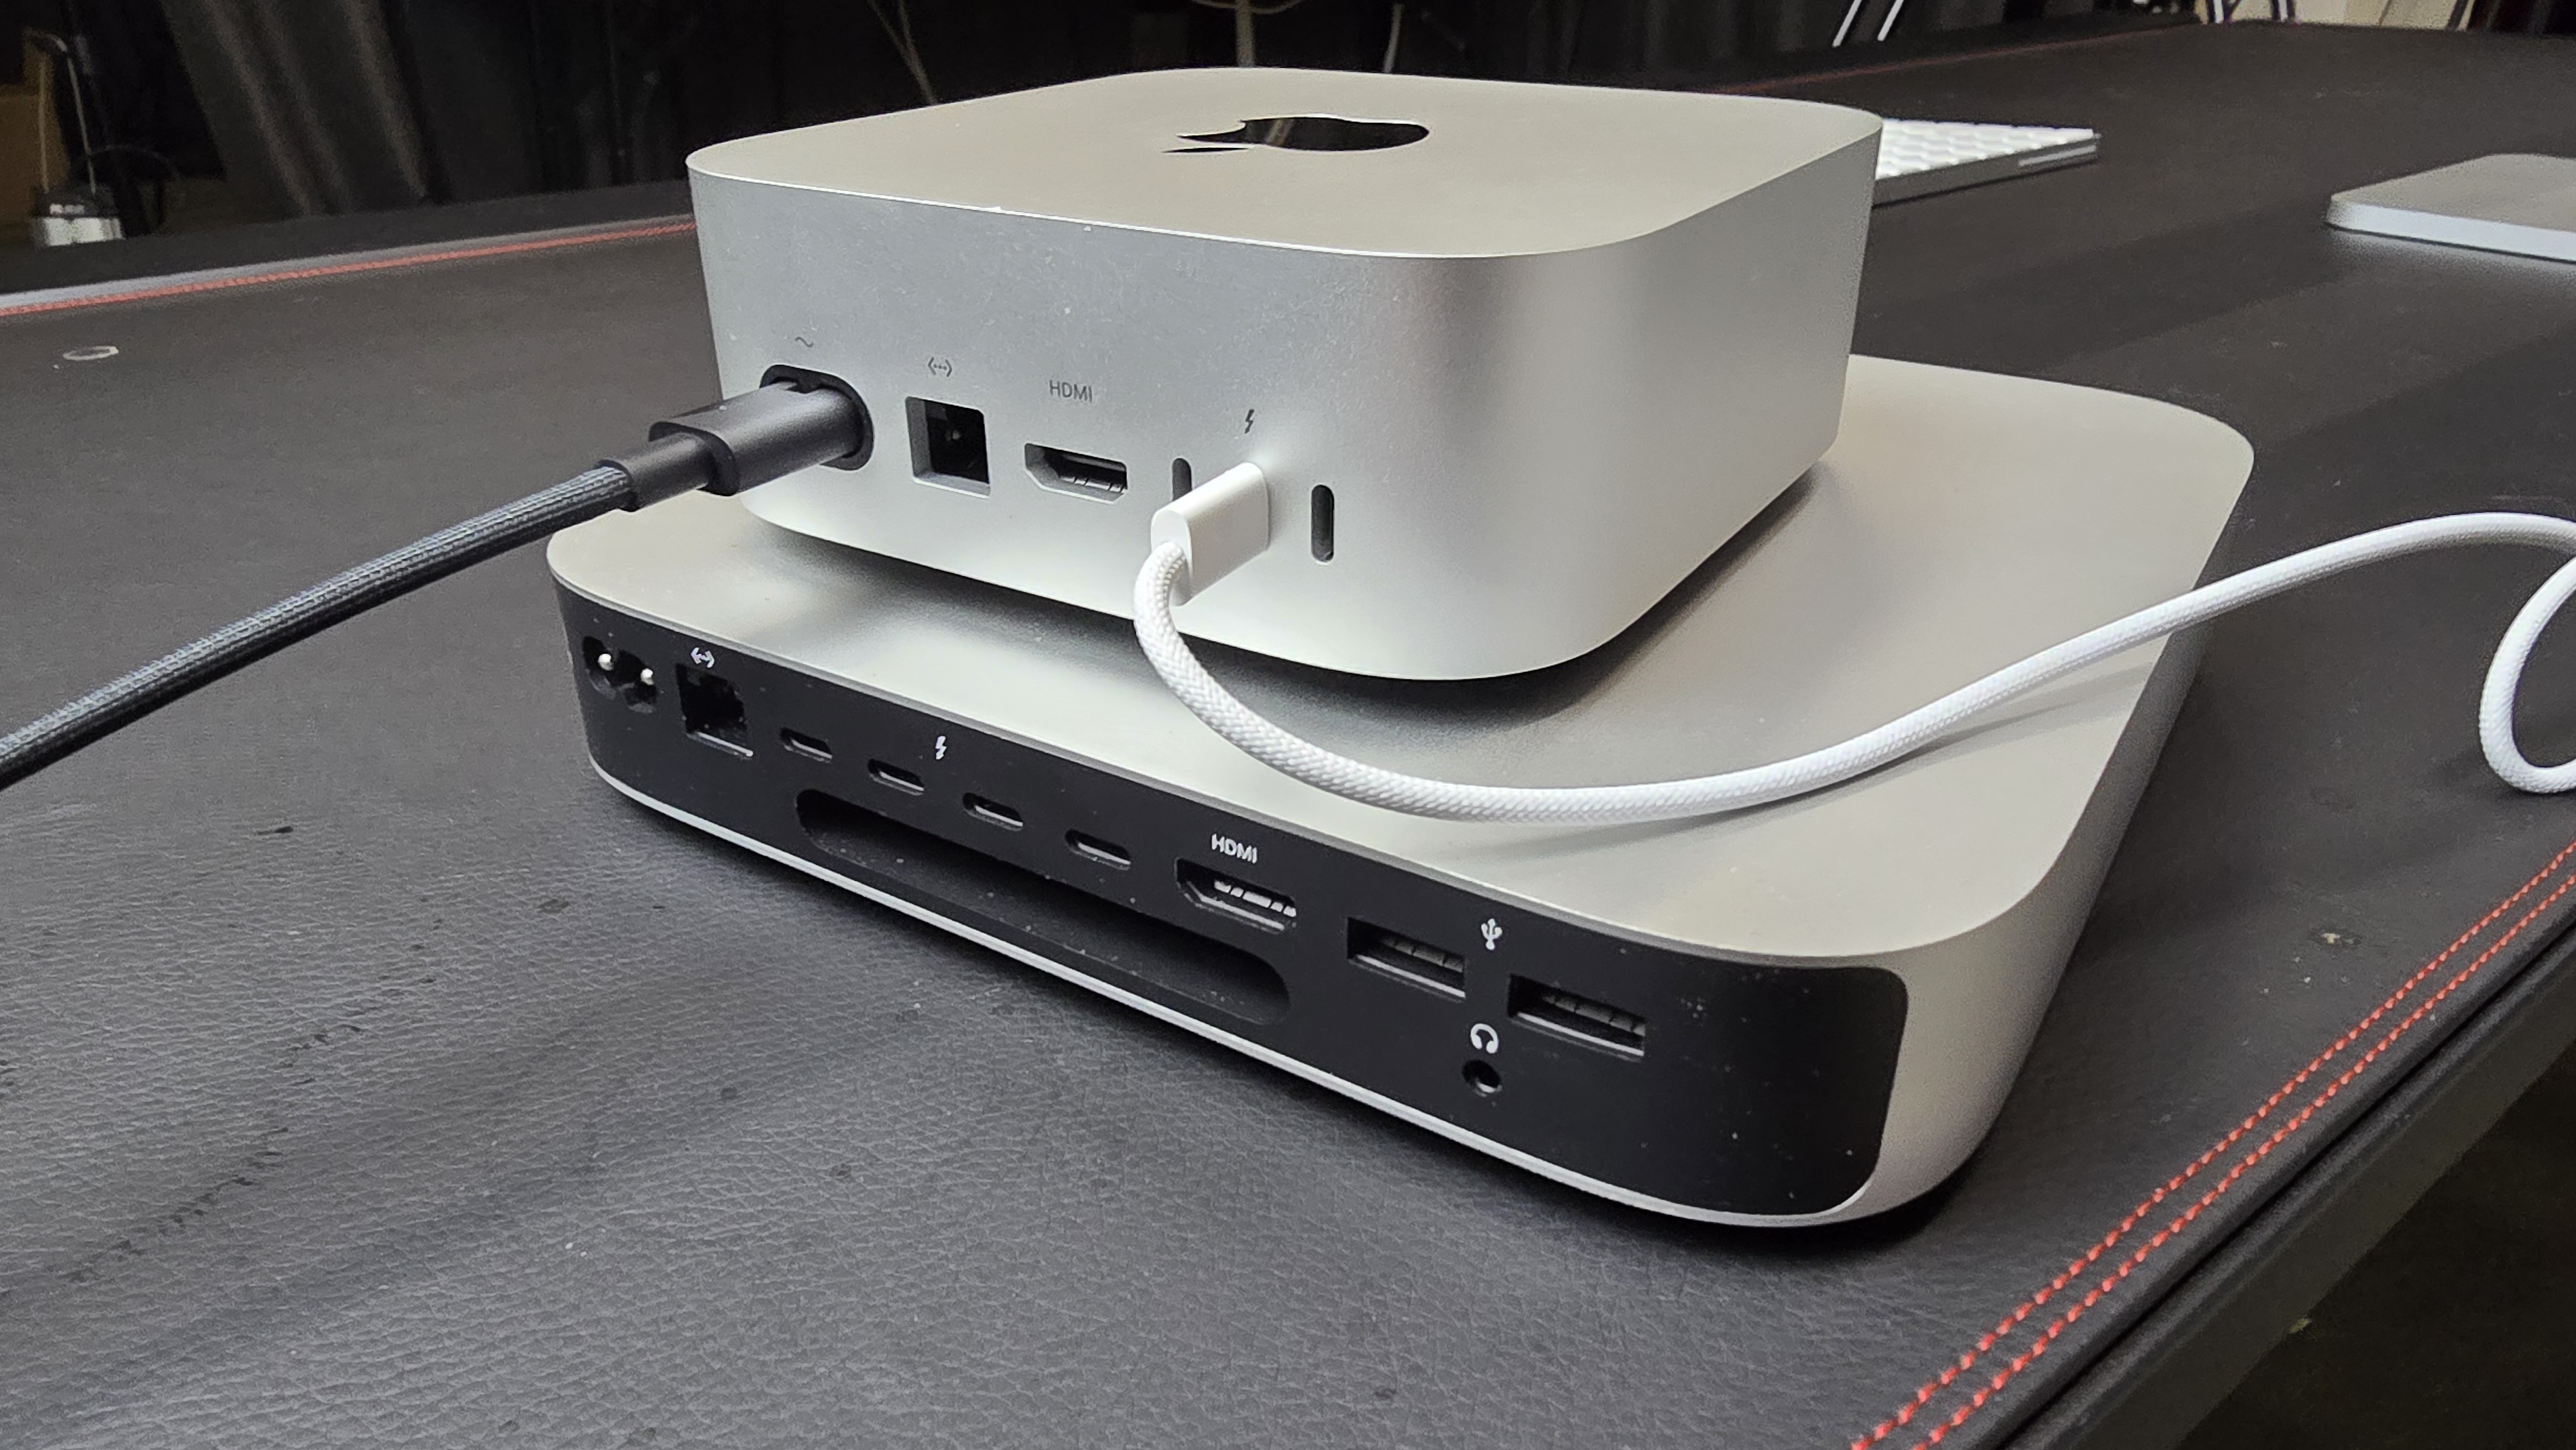 Apple Mac Mini M4
 Whisper.cpp
 Ollama
 Kokoro TTS
Models are alternatives; fit is judged on the smallest (Q4_K_M weights + ~1.8 GB runtime overhead vs device memory). Speeds are for Llama 3 8B; "est." values are estimated from memory bandwidth.
Local Voice Assistant (Whisper + Ollama + Kokoro TTS)
A fully local voice assistant - speak a question, get a spoken answer. Whisper.cpp converts your speech to text with high accuracy, Ollama runs a local LLM to generate a response, and Kokoro TTS speaks the answer back in a natural-sounding voice. Everything runs on your own hardware with no cloud dependency.
What you get
- Voice input - speak naturally, Whisper.cpp transcribes in real-time
- AI reasoning - Ollama runs a local model to understand and respond
- Voice output - Kokoro TTS speaks responses in natural-sounding voices
- Fully offline - no internet required after initial setup
- CPU-friendly - Whisper and Kokoro run efficiently on CPU
- Privacy - nothing leaves your machine
- $0/month - all open-source, no API costs
Architecture
| Component | Role |
|---|---|
| Whisper.cpp | Speech-to-text - converts voice to text |
| Ollama | LLM inference - generates text responses |
| Kokoro TTS | Text-to-speech - reads responses aloud |
| Qwen3 14B | Default model - fast, fits 12GB at Q4 |
Whisper.cpp and Kokoro TTS run efficiently on CPU (including Apple Silicon). Ollama benefits from a GPU. Recommended: RTX 3060 12GB or an Apple Mac Mini M4 (unified memory handles everything well).
Prerequisites
- Any modern computer (GPU optional for LLM)
- Python 3.10+
- Ollama installed
- A microphone
- ~10 GB free disk for models
Setup
Step 1: Install Ollama and Pull a Model
# Install from ollama.com, or:
curl -fsSL https://ollama.com/install.sh | sh

# Pull a fast model
ollama pull qwen3:14b
Step 2: Install Whisper.cpp
git clone https://github.com/ggerganov/whisper.cpp.git
cd whisper.cpp

# Build
cmake -B build && cmake --build build --config Release

# Download a medium model (good balance of speed/accuracy)
bash models/download-ggml-model.sh medium
Test transcription:
# Record a short test (requires ffmpeg)
ffmpeg -f dshow -i audio="Microphone" -t 5 test.wav
./build/bin/whisper-cli -m models/ggml-medium.bin -f test.wav
Step 3: Install Kokoro TTS
pip install kokoroTest TTS:
from kokoro import KPipeline
pipeline = KPipeline(lang_code='a')  # American English
for result in pipeline("Hello, this is your local AI assistant speaking."):
    with open('output.wav', 'wb') as f:
        f.write(result.audio)
Step 4: Wire Them Together
Save this as voice_assistant.py:
import subprocess
import tempfile
import wave
import pyaudio
import requests
from kokoro import KPipeline

OLLAMA_URL = "http://localhost:11434/api/generate"
MODEL = "qwen3:14b"
WHISPER_BIN = "./whisper.cpp/build/bin/whisper-cli"
WHISPER_MODEL = "./whisper.cpp/models/ggml-medium.bin"

tts_pipeline = KPipeline(lang_code='a')

def record_audio(duration=5, sample_rate=16000):
    p = pyaudio.PyAudio()
    stream = p.open(format=pyaudio.paInt16,
                    channels=1,
                    rate=sample_rate,
                    input=True,
                    frames_per_buffer=1024)
    frames = []
    for _ in range(0, int(sample_rate / 1024 * duration)):
        data = stream.read(1024)
        frames.append(data)
    stream.close()
    p.terminate()

    with tempfile.NamedTemporaryFile(suffix='.wav', delete=False) as f:
        wf = wave.open(f, 'wb')
        wf.setnchannels(1)
        wf.setsampwidth(p.get_sample_size(pyaudio.paInt16))
        wf.setframerate(sample_rate)
        wf.writeframes(b''.join(frames))
        wf.close()
        return f.name

def transcribe(audio_file):
    result = subprocess.run(
        [WHISPER_BIN, '-m', WHISPER_MODEL, '-f', audio_file],
        capture_output=True, text=True
    )
    return result.stdout.strip()

def ask_llm(prompt):
    response = requests.post(OLLAMA_URL, json={
        "model": MODEL,
        "prompt": prompt,
        "stream": False
    })
    return response.json()["response"]

def speak(text):
    for result in tts_pipeline(text):
        with tempfile.NamedTemporaryFile(suffix='.wav', delete=False) as f:
            f.write(result.audio)
        subprocess.run(['ffplay', '-nodisp', '-autoexit', f.name])

# Main loop
print("Listening... (speak within 5 seconds)")
audio_file = record_audio(5)
print("Transcribing...")
text = transcribe(audio_file)
print(f"You said: {text}")

print("Thinking...")
response = ask_llm(text)
print(f"AI: {response}")

print("Speaking...")
speak(response)
Step 5: Run It
pip install pyaudio requests
python voice_assistant.py
Speak into your microphone. After 5 seconds, the assistant will transcribe, think, and speak back.
Use it
Hands-Free Q&A
Ask questions while cooking, working, or debugging. "What's the capital of Mongolia?" or "How do I reverse a linked list in Python?"
Note-Taking
"Take a note: buy milk and eggs tomorrow" - pipe the transcription to a notes file instead of the LLM.
Smart Home Controller
Pair with Home Assistant APIs. "Turn off the living room lights" - the LLM generates a JSON command your home automation can execute.
Cost vs cloud
| Local Voice Assistant | Alexa / Google Assistant | |
|---|---|---|
| Monthly | $0 | $0 (with ads) |
| Privacy | Complete | Recorded and analyzed |
| Offline | Yes | No |
| Customizable | Full source | Limited skills |
| Wake word | None (push-to-talk) | Always listening |
| Voices | 10+ (Kokoro) | Limited set |
Troubleshooting
- No microphone input → Check your microphone device with
ffmpeg -list_devices true -f dshow -i dummy(Windows) orarecord -l(Linux). - Whisper is slow → Use the
tinyorbasemodel instead ofmedium. Add--threads 4for CPU parallelization. - Kokoro has no audio output → Install ffplay (
ffmpegpackage) or use a different audio playback library. - LLM response is too slow for voice → Use a smaller model like Llama 3.1 8B or Phi-4 mini. Set
num_predict: 128to limit response length. - Audio quality issues → Use a USB microphone instead of built-in. Adjust
sample_rateto 16000.
Swap components
- Faster STT → Use Whisper tiny instead of medium for near-real-time transcription.
- Better TTS voice → Try Piper TTS for different voice styles.
- Web UI → Integrate with Open WebUI which has built-in voice input/output support.
- Always-on mode → Add wake word detection with Porcupine or use push-to-talk with a button.
- Better LLM on Apple Silicon → Use MLX for optimized Apple Silicon inference.
Frequently asked
What is the Local Voice Assistant (Whisper + Ollama + Kokoro TTS) stack for?
Whisper.cpp + Ollama + Kokoro TTS = a fully local voice assistant. Speak, get AI answers spoken back. No cloud, no wake-word fees, runs on CPU. $0/mo. It is purpose-built for Build a private, always-on voice assistant that runs entirely on your hardware and runs entirely on your own hardware.
How much does the Local Voice Assistant (Whisper + Ollama + Kokoro TTS) stack cost?
Local Voice Assistant (Whisper + Ollama + Kokoro TTS) costs about $199 for the cheapest listed device that fits (NVIDIA RTX 3060 12GB) up front and $0/month to run, since everything is self-hosted — no per-token or subscription fees versus a cloud equivalent.
How long does it take to set up Local Voice Assistant (Whisper + Ollama + Kokoro TTS)?
Plan for roughly 30 minutes. The stack is rated advanced.
What do I need to run Local Voice Assistant (Whisper + Ollama + Kokoro TTS)?
Local Voice Assistant (Whisper + Ollama + Kokoro TTS) is built from 3 tool(s), 2 model(s), 2 hardware item(s). Each is listed below with a link.