Visual AI Agent Builder (Langflow + Ollama)
Visual AI Agent Builder (Langflow + Ollama) is a local AI stack for Prototype and deploy multi-agent RAG applications visually with local models. Langflow + Ollama = visual drag-and-drop framework for building multi-agent and RAG applications. Prototype complex AI pipelines in minutes, export as APIs, all running locally. It combines 6 components, is rated intermediate, and takes about 15 minutes to set up. Expect about $199 for the cheapest listed device that fits (NVIDIA RTX 3060 12GB) and $0/month versus cloud.
- Cost
- $199
- NVIDIA RTX 3060 12GB · $0/mo vs cloud
- Difficulty
- intermediate
- Setup time
- ~15 min
- Use case
- Prototype and deploy multi-agent RAG applications visually with local models
What's in this stack
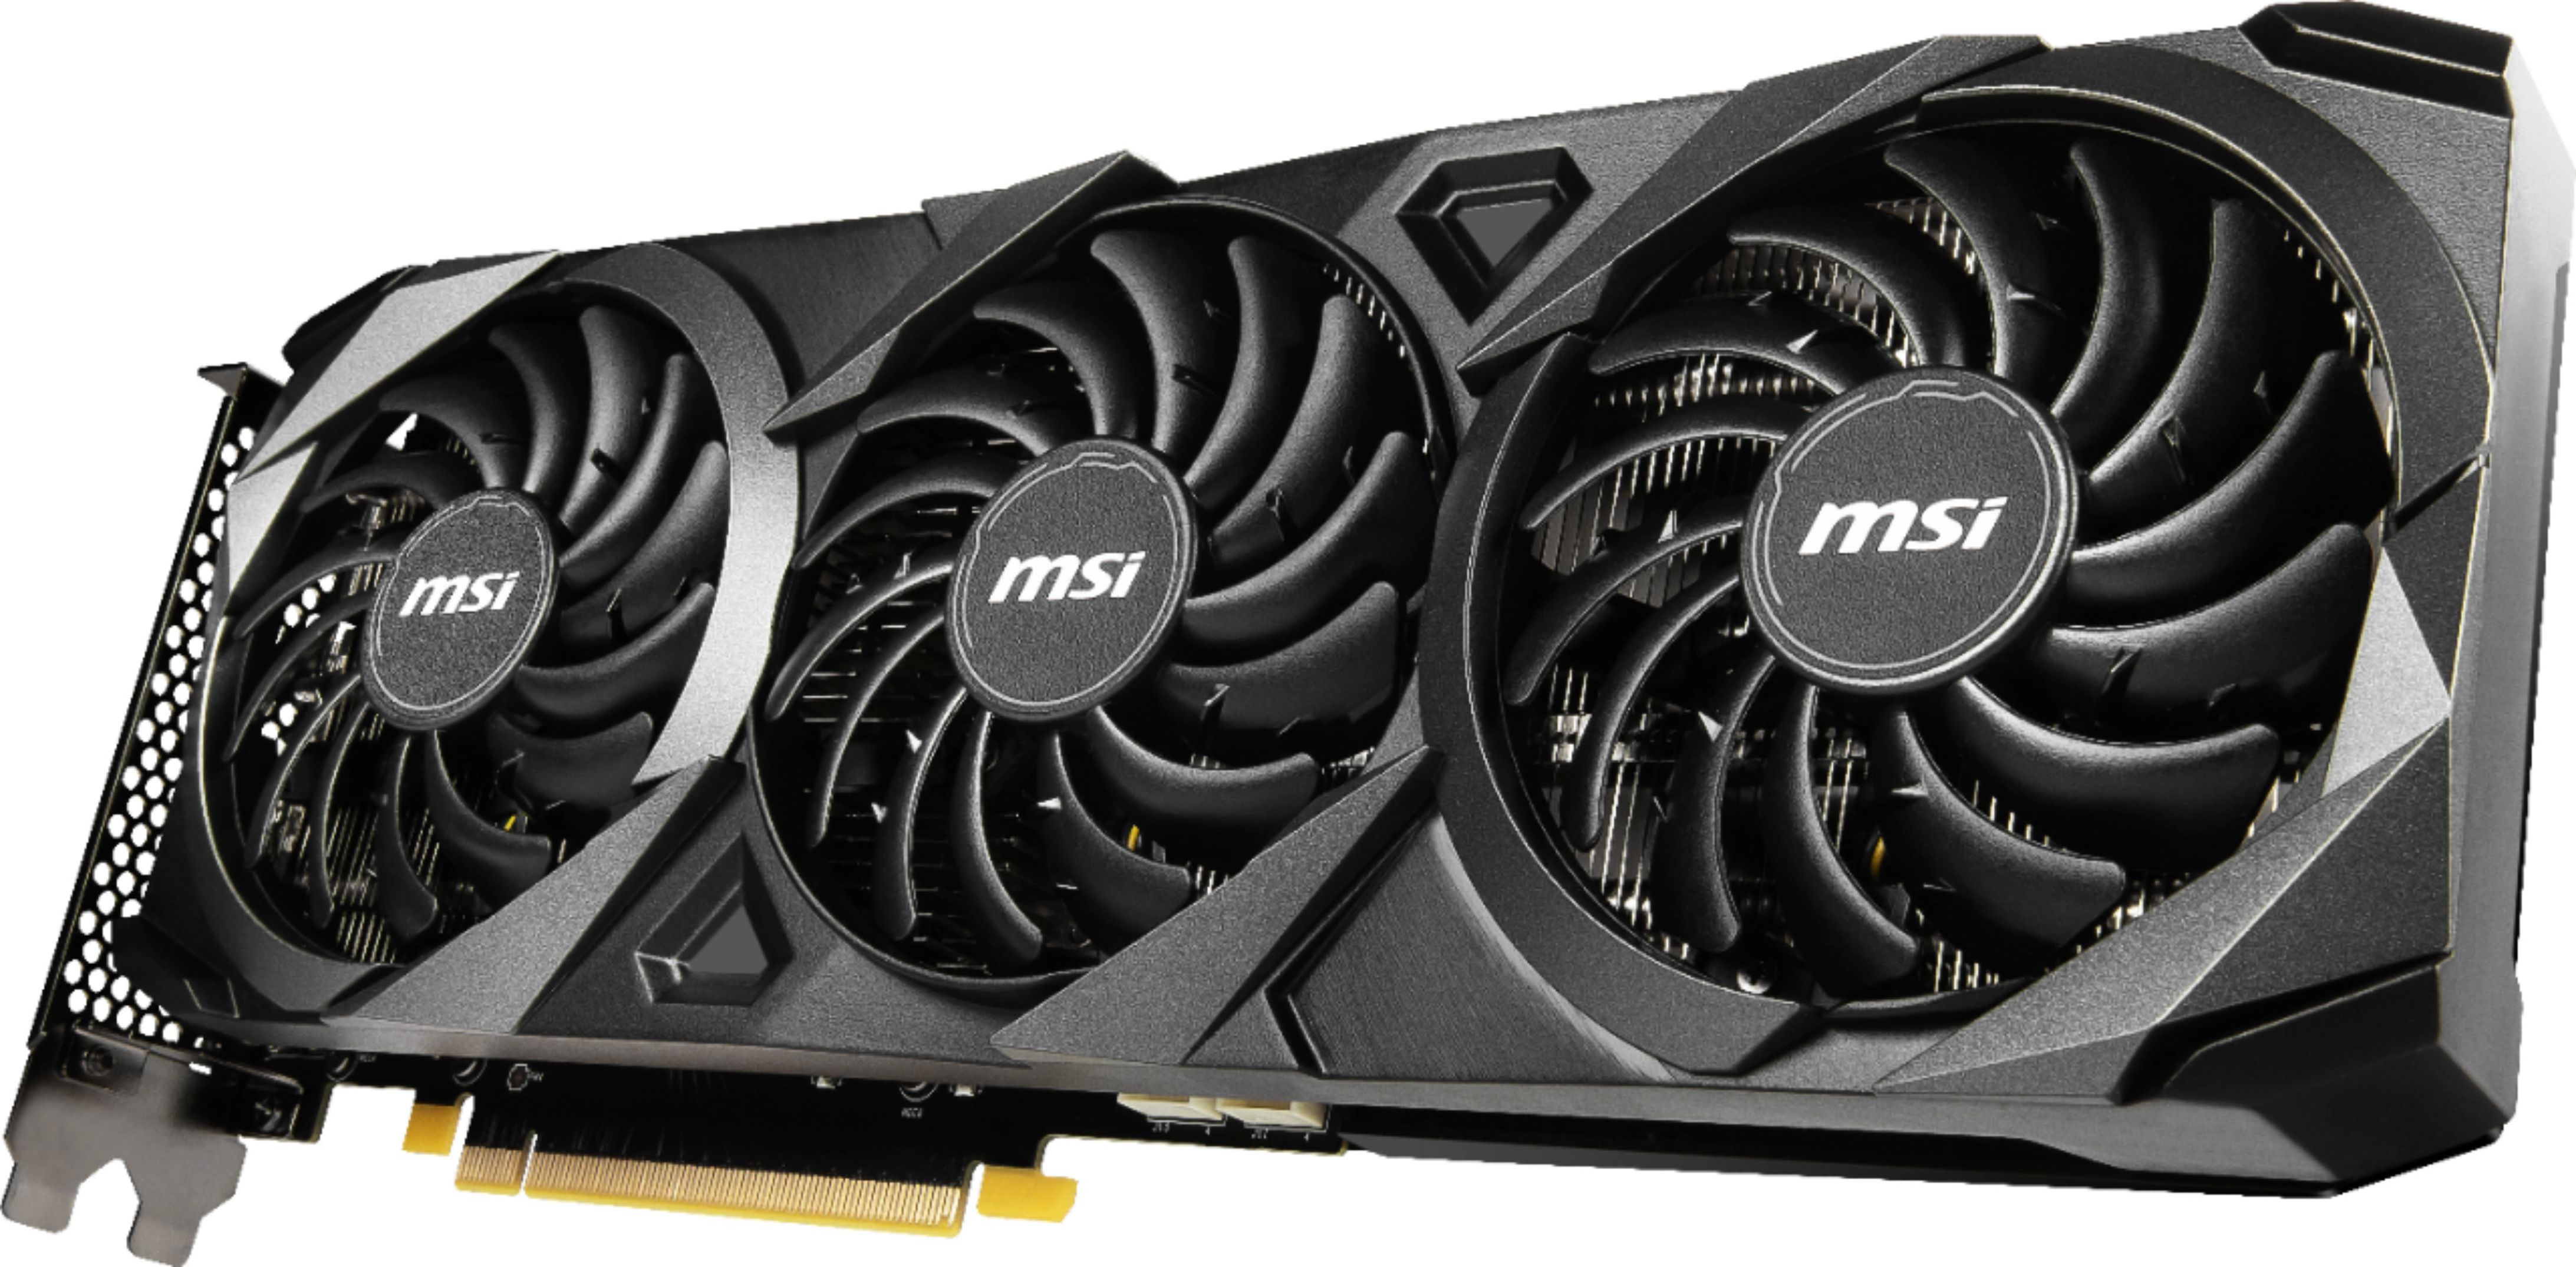 NVIDIA RTX 3060 12GB
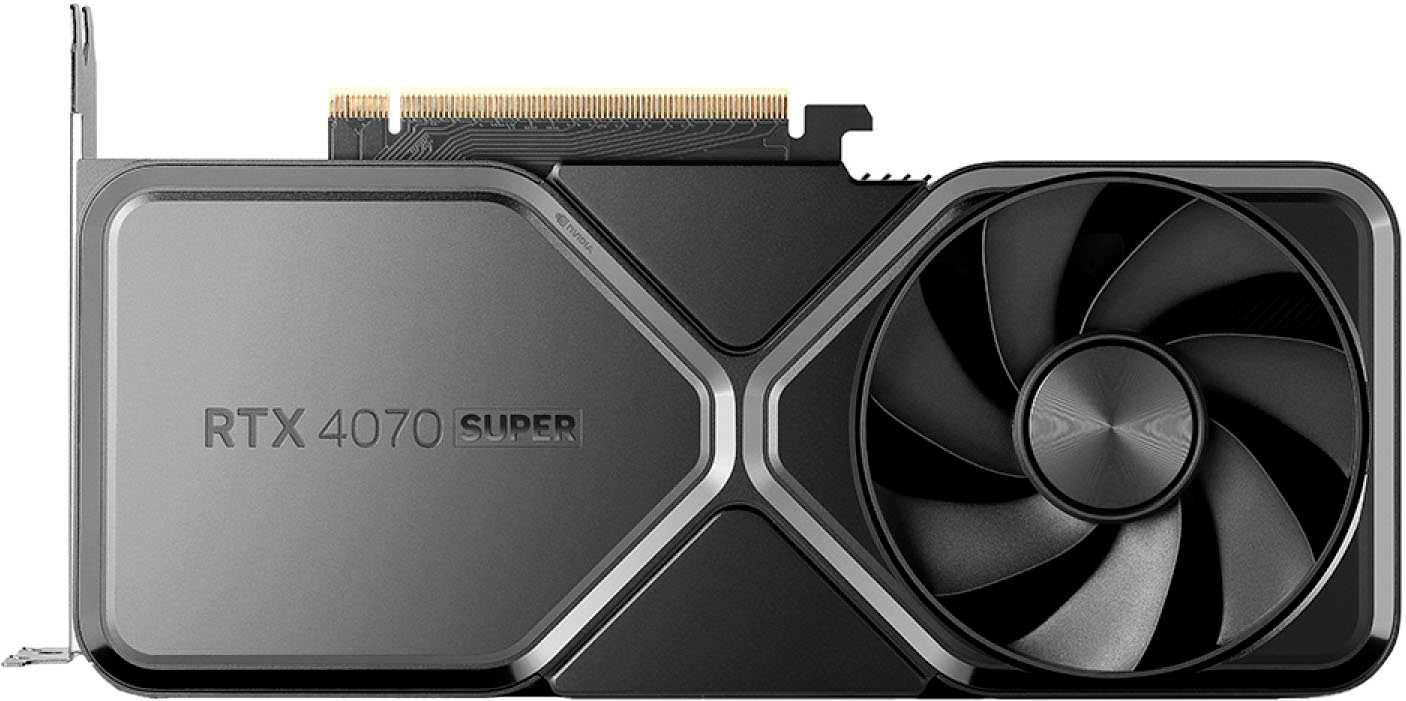 NVIDIA RTX 4070 Super
 Langflow
 Ollama
Models are alternatives; fit is judged on the smallest (Q4_K_M weights + ~1.8 GB runtime overhead vs device memory). Speeds are for Llama 3 8B; "est." values are estimated from memory bandwidth.
Visual AI Agent Builder (Langflow + Ollama)Link to this section
A low-code visual framework for building AI applications. Langflow gives you a drag-and-drop canvas to construct multi-agent systems, RAG pipelines, and chatbot workflows - then export them as production-ready APIs. Connect it to Ollama for local model inference, and you can prototype and deploy complex AI pipelines entirely on your own hardware.
Langflow's real-time visual feedback shows data flowing between nodes as you build, making it one of the most intuitive tools for designing AI agent architectures.
What you getLink to this section
- Drag-and-drop AI canvas - visually connect LLMs, vector stores, agents, and tools
- Multi-agent orchestration - build systems with multiple specialized agents that collaborate
- RAG pipeline builder - document ingestion, chunking, embedding, retrieval, all visual
- Real-time testing - run individual nodes or full flows and see data flow live
- Export as API - every flow gets a REST API endpoint you can call from your app
- MCP support - connect Model Context Protocol servers as tools for your agents
- $0/mo - all local, no API keys needed
ArchitectureLink to this section
| Component | Role |
|---|---|
| Langflow | Visual flow builder and API server |
| Ollama | Serves local LLM models |
| Qwen3 14B | Default general-purpose model, fits 12GB |
| Built-in vector store | Document embeddings for RAG (Chroma/LanceDB) |
Recommended GPU: RTX 3060 12GB for 14B models, or RTX 4070 Super for Qwen3 30B A3B (MoE, fast).
PrerequisitesLink to this section
- A GPU with ≥12 GB VRAM for local LLM inference (CPU-only mode works for flow prototyping)
- Python 3.10+ or Docker
- 4 GB RAM minimum
- ~5 GB free disk
SetupLink to this section
Option A: Docker (Recommended)Link to this section
Save this as docker-compose.yml:
services:
  ollama:
    image: ollama/ollama:latest
    container_name: ollama
    volumes:
      - ollama:/root/.ollama
    ports:
      - "11434:11434"
    deploy:
      resources:
        reservations:
          devices:
            - driver: nvidia
              count: all
              capabilities: [gpu]
    restart: unless-stopped

  langflow:
    image: langflowai/langflow:latest
    container_name: langflow
    depends_on:
      - ollama
    ports:
      - "7860:7860"
    volumes:
      - langflow_data:/app/langflow
    environment:
      - LANGFLOW_AUTO_LOGIN=true
    restart: unless-stopped

volumes:
  ollama:
  langflow_data:
Launch it:
docker compose up -d
docker exec ollama ollama pull qwen3:14b
Open http://localhost:7860 to access Langflow.
Option B: pip InstallLink to this section
pip install langflow
langflow run
Then install and run Ollama separately:
# Install Ollama from https://ollama.com
ollama pull qwen3:14b
Open http://localhost:7860 for Langflow.
Connect Langflow to OllamaLink to this section
In Langflow, add these components to your flow:
- Ollama Chat Model - set Base URL to
http://ollama:11434(Docker) orhttp://localhost:11434(pip) - Select model:
qwen3:14b - Connect it to a Prompt node and Chat Output for a basic chatbot
Use itLink to this section
Build a Chatbot with RAGLink to this section
- Drag in: File → Ollama Embeddings → Vector Store (Chroma) → Ollama Chat Model → Chat Output
- Upload a PDF to the File component
- Ask questions about the document - answers come from your local knowledge base
- Export as API endpoint for your frontend
Multi-Agent Research SystemLink to this section
- Create a Agent node with a Web Search Tool connected to Ollama
- Add a second Agent node for summarization
- Use a Chat Input to receive the query, route through both agents
- The search agent gathers info, the summary agent condenses it
Document Processing PipelineLink to this section
- Combine File Loader → Splitter → Ollama Embeddings → Vector Store
- Add Ollama Chat Model with a custom prompt template
- Build a question-answering system over your documents
Cost vs cloudLink to this section
| Local Langflow + Ollama | Langflow Cloud + OpenAI | |
|---|---|---|
| Monthly | $0 | $50-200+ API costs |
| Hardware | ~$300-600 once (GPU) | $0 |
| Data privacy | Stays on your machine | Sent to cloud |
| Prototyping speed | Instant (local network) | Dependent on API |
| AI calls | Unlimited, free | Per-token billing |
| Break-even | ~2-6 months | - |
TroubleshootingLink to this section
- Langflow shows "Model not found" → Make sure the model name matches exactly what you pulled in Ollama. Run
docker exec ollama ollama listto see available models. - Slow responses → For faster inference, try Qwen3 30B A3B (MoE - only 3B active parameters per token) or a smaller model like Llama 3.1 8B.
- Can't upload files → Langflow stores uploads in its container volume. For larger files, mount a host directory.
- Docker networking → If Langflow can't reach Ollama, use
http://host.docker.internal:11434(Docker Desktop) or the container nameollama:11434(same compose file).
Swap componentsLink to this section
- Use Qdrant instead of Chroma → Add Qdrant as a Docker service and use the Qdrant vector store component.
- Hybrid cloud/local → Add an OpenAI or Anthropic component alongside Ollama for different tasks.
- Try Flowise → Flowise is a similar visual builder with a different node design philosophy.
- Production API → Set
LANGFLOW_AUTO_LOGIN=falseand configure authentication via environment variables.
Frequently asked
What is the Visual AI Agent Builder (Langflow + Ollama) stack for?
Langflow + Ollama = visual drag-and-drop framework for building multi-agent and RAG applications. Prototype complex AI pipelines in minutes, export as APIs, all running locally. It is purpose-built for Prototype and deploy multi-agent RAG applications visually with local models and runs entirely on your own hardware.
How much does the Visual AI Agent Builder (Langflow + Ollama) stack cost?
Visual AI Agent Builder (Langflow + Ollama) costs about $199 for the cheapest listed device that fits (NVIDIA RTX 3060 12GB) up front and $0/month to run, since everything is self-hosted — no per-token or subscription fees versus a cloud equivalent.
How long does it take to set up Visual AI Agent Builder (Langflow + Ollama)?
Plan for roughly 15 minutes. The stack is rated intermediate.
What do I need to run Visual AI Agent Builder (Langflow + Ollama)?
Visual AI Agent Builder (Langflow + Ollama) is built from 2 tool(s), 2 model(s), 2 hardware item(s). Each is listed below with a link.