DiffusionGemma Local
DiffusionGemma Local is a local AI stack for High-speed local text generation. Run Google’s DiffusionGemma 26B A4B locally for faster text generation on a consumer GPU. Ideal for builders who want low-latency local inference. It combines 4 components, is rated advanced, and takes about 35 minutes to set up. Expect about $1,599 for the cheapest listed device that fits (NVIDIA RTX 4090) and $0/month versus cloud.
- Cost
- $1,599
- NVIDIA RTX 4090 · $0/mo vs cloud
- Difficulty
- advanced
- Setup time
- ~35 min
- Use case
- High-speed local text generation
What's in this stack
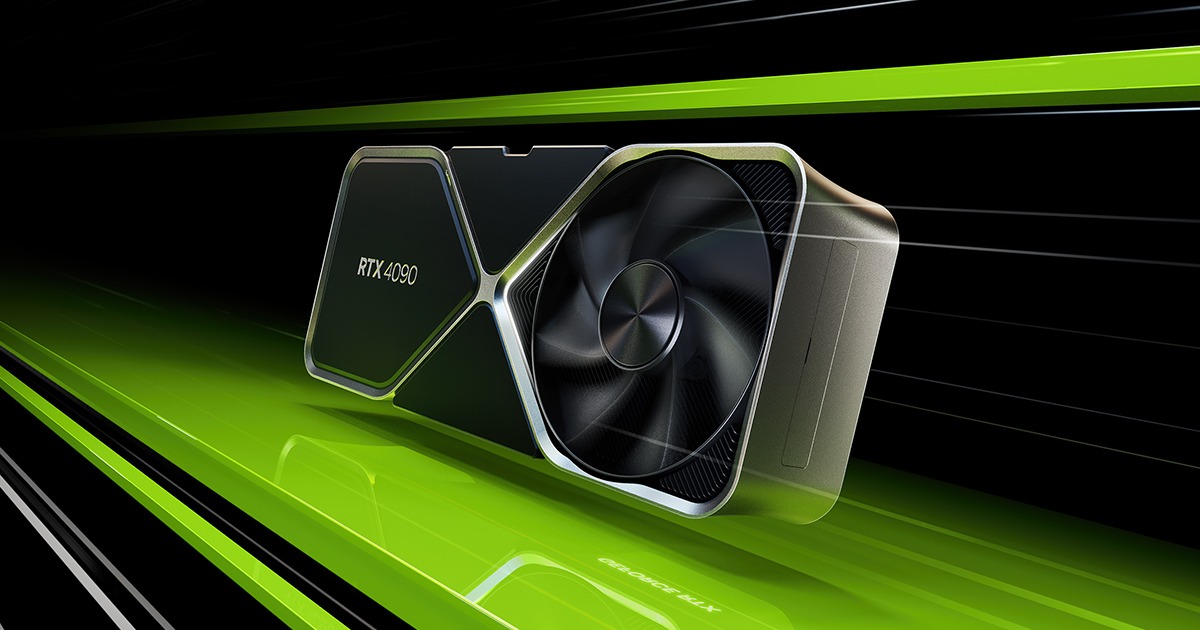 NVIDIA RTX 4090
 Ollama
 llama.cpp
Models are alternatives; fit is judged on the smallest (Q4_K_M weights + ~1.8 GB runtime overhead vs device memory). Speeds are for Llama 3 8B; "est." values are estimated from memory bandwidth.
DiffusionGemma Local
This stack runs Google’s new DiffusionGemma 26B A4B locally. The model generates text in parallel rather than token-by-token, so it can be much faster for local inference on a capable GPU.
What you get
- High-speed local text generation
- Parallel inference on a consumer GPU
- A lower-latency local writer than autoregressive-only stacks
Architecture
| Component | Role |
|---|---|
| Ollama | Local model hosting and API |
| llama.cpp | Optional fallback and GGUF execution |
| Gemma 4 26B A4B | Fast diffusion-style text model |
Prerequisites
- A high-end GPU such as RTX 4090
- 80+ GB free disk for model storage and caches
- Docker or native
ollamainstall
Setup
- Install Ollama.
brew install ollama- Pull the DiffusionGemma model.
ollama pull gemma-4:26b-a4b- Start local inference.
ollama serve- Connect an AI client or API caller to
http://localhost:11434.
Use it
- Local writing for content, emails, and planning.
- Rapid ideation when you need more throughput than traditional token loops.
- Offline experimentation with the latest Google open model.
Cost vs cloud
| Local | Cloud | |
|---|---|---|
| Monthly | $0 | $20+ |
| Hardware | $2200 once | $0 |
| Throughput | High | Variable |
Troubleshooting
- Model pull stalls → check network and disk; the A4B model is large.
- Slow generation → confirm your GPU is engaged and not CPU fallback.
- Compatibility issue → try
llama.cppwith the GGUF copy if Ollama fails.
Swap components
- Use LM Studio if you prefer a local desktop UI.
- For smaller GPU budgets, use Gemma 4 12B instead.
Frequently asked
What is the DiffusionGemma Local stack for?
Run Google’s DiffusionGemma 26B A4B locally for faster text generation on a consumer GPU. Ideal for builders who want low-latency local inference. It is purpose-built for High-speed local text generation and runs entirely on your own hardware.
How much does the DiffusionGemma Local stack cost?
DiffusionGemma Local costs about $1,599 for the cheapest listed device that fits (NVIDIA RTX 4090) up front and $0/month to run, since everything is self-hosted — no per-token or subscription fees versus a cloud equivalent.
How long does it take to set up DiffusionGemma Local?
Plan for roughly 35 minutes. The stack is rated advanced.
What do I need to run DiffusionGemma Local?
DiffusionGemma Local is built from 2 tool(s), 1 model(s), 1 hardware item(s). Each is listed below with a link.