Best local LLMs for 16GB VRAM
Top picks for 16 GB: A.X-K2, Qwen3.5 9B, Qwen3.5 4B. 24 benchmarked models fit at Q4.
Fits = Q4_K_M + ~1.8 GB overhead ≤ 16 GB · updated every refresh
Ranked by measured benchmarks
| # | Model | Score | Q4 size | Headroom | Run it |
|---|---|---|---|---|---|
| 1 | A.X-K2 | 69GPQA | 12 GB | +2.2 GB | setup → |
| 2 | Qwen3.5 9B | 60GPQAMMLU | 6 GB | +8.2 GB | setup → |
| 3 | Qwen3.5 4B | 43GPQAMMLU | 3 GB | +11.2 GB | setup → |
| 4 | Muse Glimmer | 42AAArenaGPQA | 10 GB | +4.2 GB | setup → |
| 5 | Ling 3.0 Tiny | 32GPQA | 5 GB | +9.2 GB | setup → |
| 6 | MiniCPM5-2B | 27GPQA | 1 GB | +13.2 GB | setup → |
| 7 | NVIDIA-Nemotron-Nano-9B-v2 | 27GPQAMMLU | 5 GB | +9.2 GB | setup → |
| 8 | gpt-oss-20b | 26ArenaGPQAMMLU | 12 GB | +2.2 GB | setup → |
| 9 | Nemotron 3.5 Lightning | 26AAGPQA | 10 GB | +4.2 GB | setup → |
| 10 | Gemma 4 12B | 24GPQA | 7 GB | +7.2 GB | setup → |
| 11 | Mistral Small 4 | 24AAGPQA | 8 GB | +6.2 GB | setup → |
| 12 | Qwen3-4B-Instruct-2507 | 21GPQAMMLU | 2 GB | +12.2 GB | setup → |
| 13 | Phi-4 | 19ArenaGPQAMMLU | 8.5 GB | +5.7 GB | ollama run phi-4:14b |
| 14 | Granite 4.2 3B | 16AAArenaGPQA | 2 GB | +12.2 GB | setup → |
| 15 | Olmo-3-7B-Think | 15GPQA | 4 GB | +10.2 GB | setup → |
Also fits, not benchmarked yet
Qwen3 14BSmolLM2-135MQwen2.5-Coder-14B-InstructNVIDIA-Nemotron-3-Nano-4B-BF16Qwen2.5-0.5BKimi-K3-DSparkMiniCPM5-2B-DSparkQwen2.5-14B-Instruct
GPUs with 16 GB–23 GB

Intel Arc A770 16GB
16 GB · 560 GB/s
~65 tok/s est. Llama 3 8B
$229

AMD Radeon RX 7600 XT
16 GB · 288 GB/s
~35 tok/s est. Llama 3 8B
$309
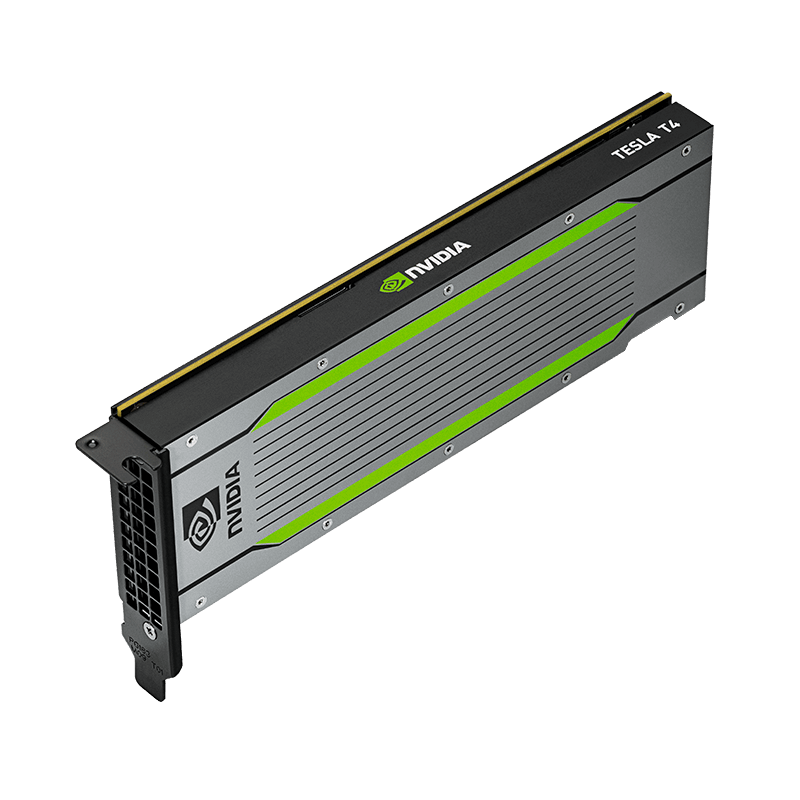
NVIDIA Tesla T4
16 GB · 320 GB/s
~35 tok/s est. Llama 3 8B
$349

AMD Radeon RX 7800 XT
16 GB · 624 GB/s
~75 tok/s est. Llama 3 8B
$449
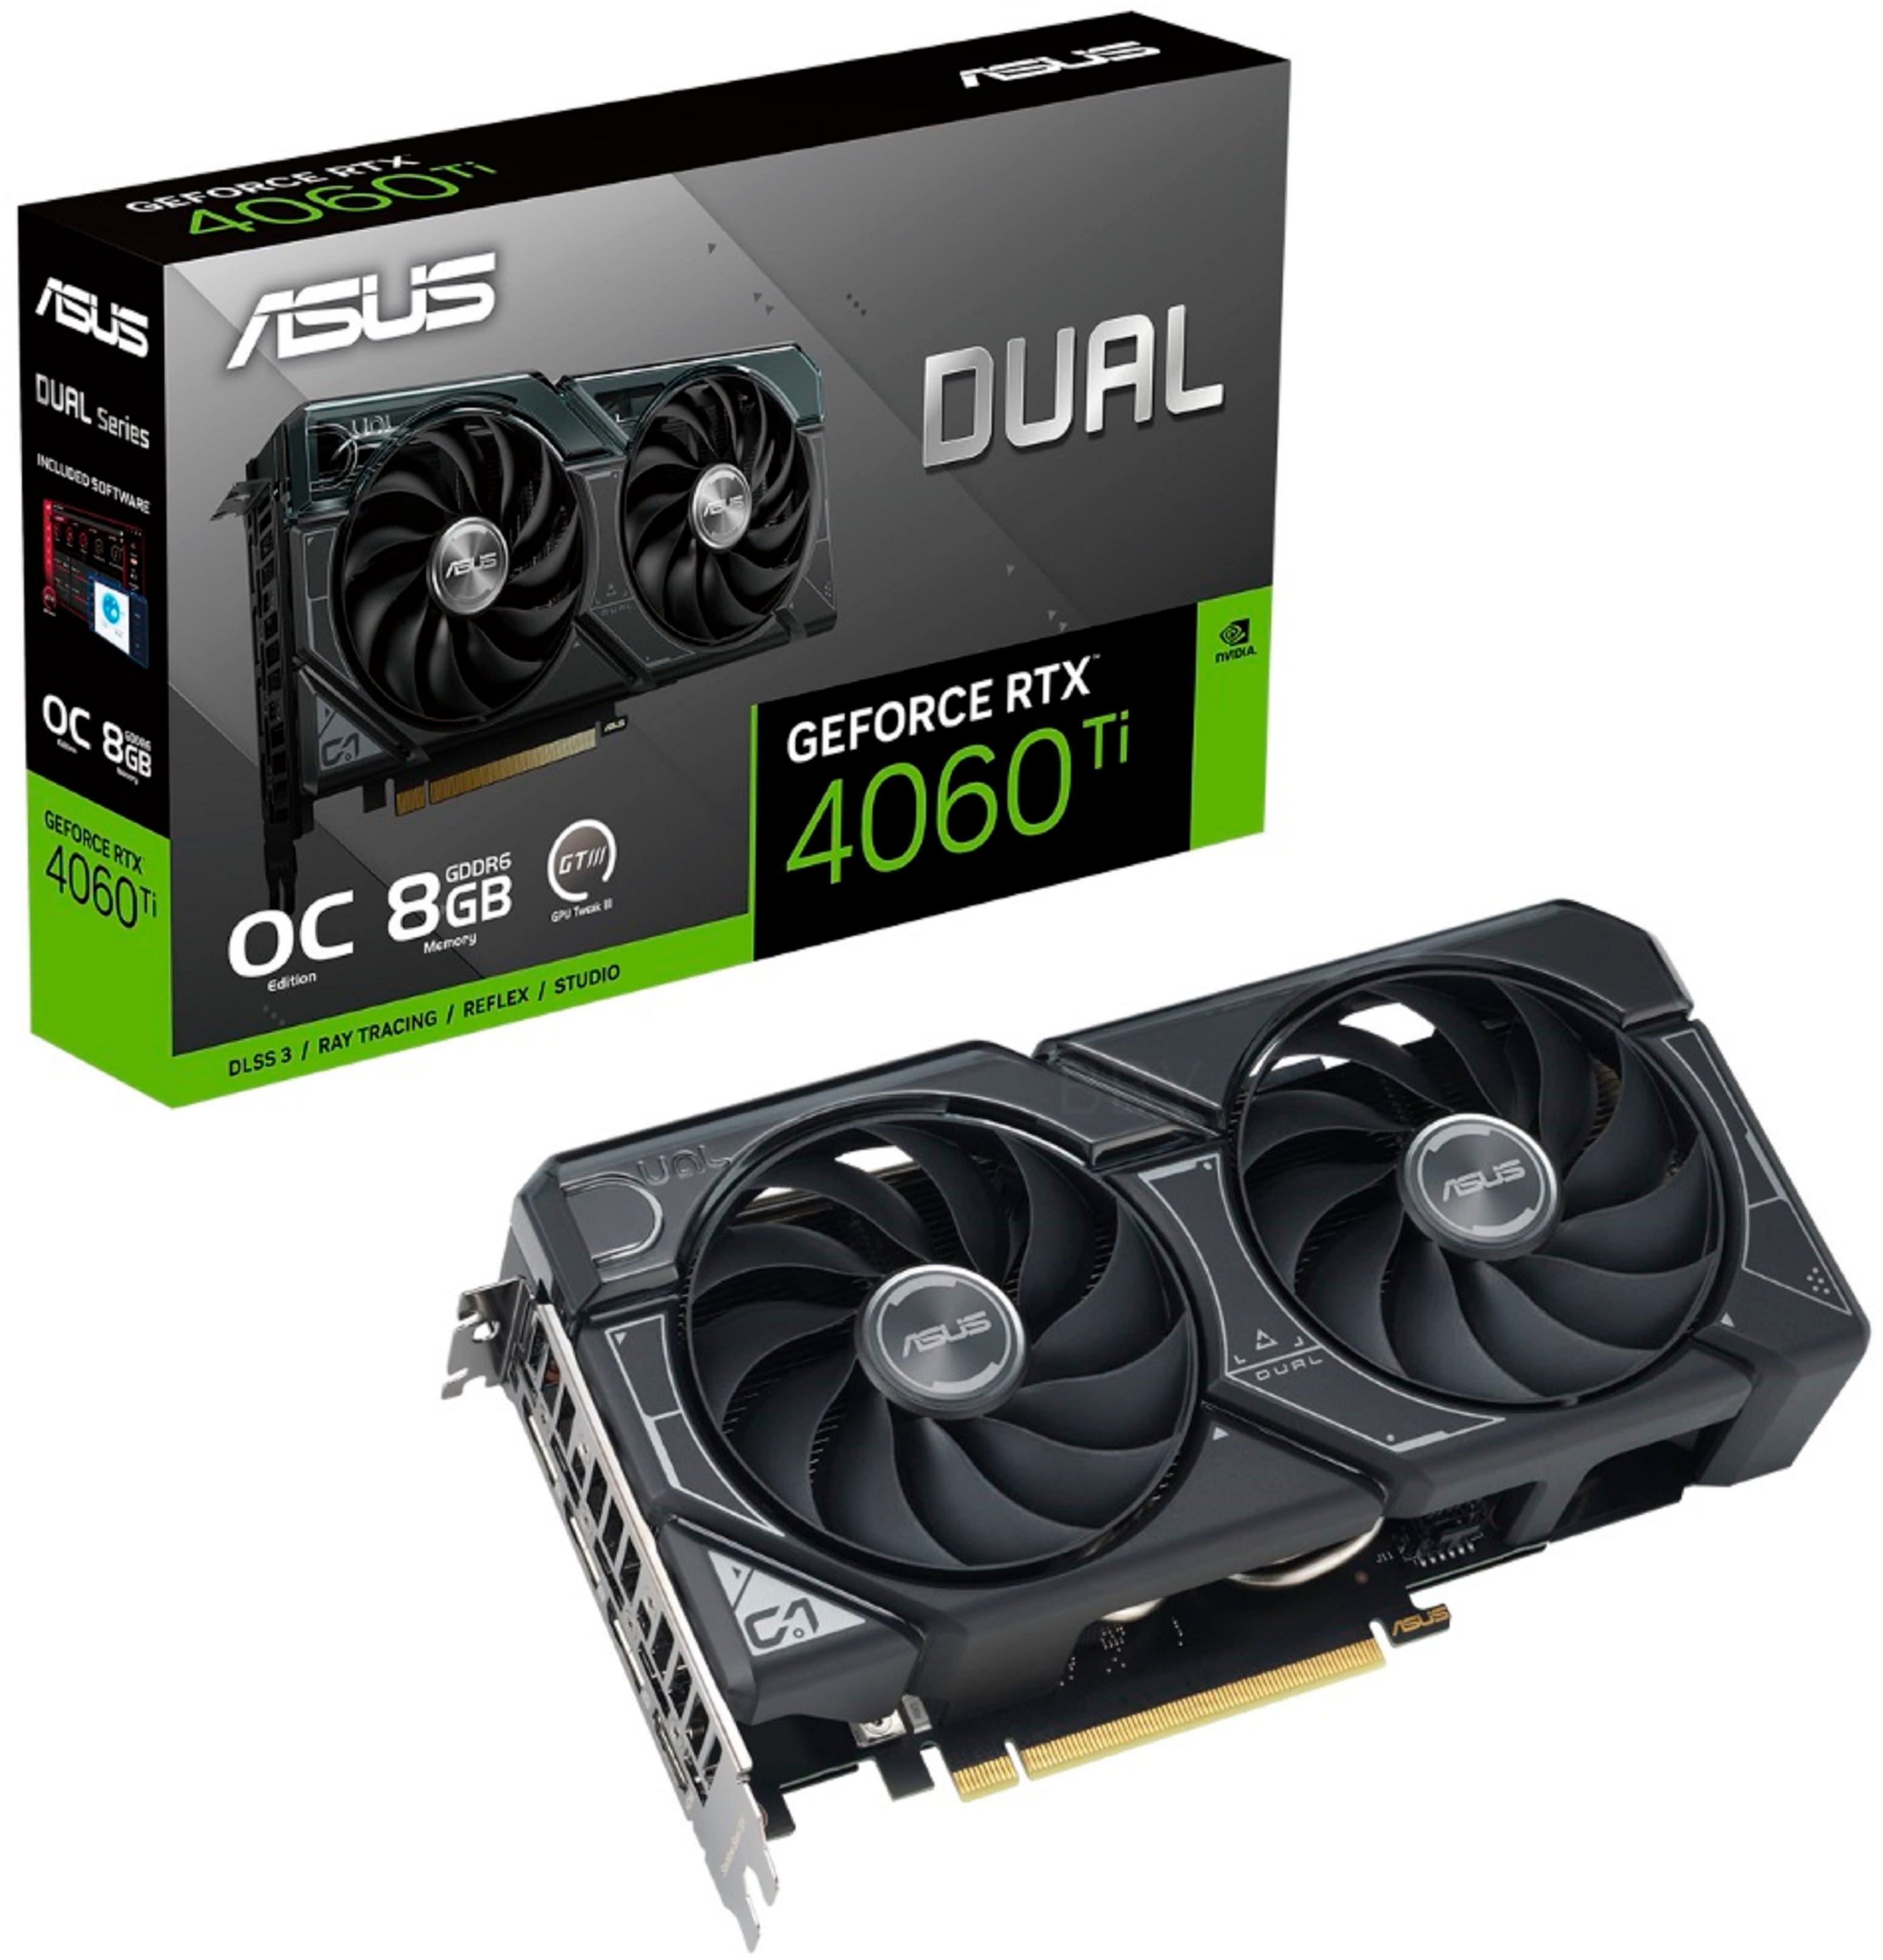
NVIDIA RTX 4060 Ti 16GB
16 GB · 288 GB/s
~35 tok/s est. Llama 3 8B
$449

AMD Radeon RX 9070
16 GB · 512 GB/s
~60 tok/s est. Llama 3 8B
$499

NVIDIA RTX 5060 Ti
16 GB · 448 GB/s
~50 tok/s est. Llama 3 8B
$499

AMD Radeon RX 9070 XT
16 GB · 640 GB/s
~75 tok/s est. Llama 3 8B
$599
Frequently asked
What is the best LLM for 16GB of VRAM?
By measured benchmarks, A.X-K2, Qwen3.5 9B, Qwen3.5 4B lead the models that fit 16 GB at Q4_K_M quantization.
How is "fits" decided?
A model fits when its Q4_K_M weights plus about 1.8 GB of runtime overhead (KV cache, activations) are at or under 16 GB. Long contexts need more; use the VRAM calculator for an exact figure.
How are the models ranked?
Each model's score averages the measured signals it has - Artificial Analysis index, LMArena rating, GPQA, MMLU-Pro - as percentiles across all chat models. Models without any measured benchmark are listed separately, not ranked.